Defining the Enterprise AI Agent: A Practical Framework for Regulated Industries
The conversation around artificial intelligence in the enterprise has matured rapidly. We have moved past the era of generic chatbots and broad AI promises into something far more specific and consequential: purpose-built AI agents. But when you are building for a regulated enterprise — healthcare, telecom, financial services — the stakes are different. You cannot afford ambiguity. You need defined agents, clear boundaries, measurable outcomes, and rigorous governance.
This article breaks down what enterprise AI agents actually look like in practice, where they fail, how they differ from what came before, and what it takes to deploy them responsibly in environments where errors carry real consequences.
What Is an Enterprise AI Agent?
An AI agent is not simply a chatbot with a better interface. It is a system with a defined purpose, access to specific data sources or tools, and the ability to reason, retrieve, and act within a set of boundaries. The word "agent" implies autonomy — but in an enterprise context, particularly in regulated industries, that autonomy must be bounded, monitored, and validated.
Think of it less like a self-driving car and more like a highly capable specialist who has been given a specific brief, access to the right documents, and a clear escalation path when something falls outside their remit.
With that framing in mind, let's look at three concrete agent types that are showing up in real enterprise deployments today
Agent Type 1: The RAG Agent — Your Intelligent Knowledge Layer
What it is: The Retrieval-Augmented Generation (RAG) agent is tasked with absorbing internal documents and making them queryable. Built on a vector database or a knowledge graph, it functions as an intelligent data store — one that doesn't just search for keywords but understands context and retrieves relevant content in response to natural language queries.
In a healthcare environment, this might mean ingesting clinical guidelines, compliance policies, and internal protocols. In telecom, it could be regulatory filings, network documentation, and customer service playbooks. The RAG agent becomes the institutional memory that employees can actually have a conversation with.
At inferagents.ai, our no-code platform is built specifically to make this type of agent accessible and enterprise-ready. It integrates directly with SharePoint, supports multiple document formats, and includes pre-defined widgets that allow teams to tune retrieval behavior and guide how queries are interpreted — without requiring deep technical expertise to configure.
What can go wrong: The RAG agent's primary vulnerability is retrieval accuracy. Specifically:
- Wrong chunk retrieval — the agent pulls content from the wrong section of a document, or misses critical context that sits just outside the retrieved window
- Domain confusion — in organizations with overlapping subject areas, similar terminology across different policy domains can cause the agent to conflate distinct guidance
- Stale content — if document ingestion is not kept current, the agent may confidently retrieve outdated information
- False certainty — the response sounds authoritative even when the underlying retrieval was weak or mismatched
In regulated industries, these are not minor inconveniences. A compliance officer acting on incorrectly retrieved regulatory guidance, or a clinician referencing an outdated protocol, represents real organizational risk. This is why tuning, testing, and continuous monitoring of the RAG agent is not optional — it is foundational.
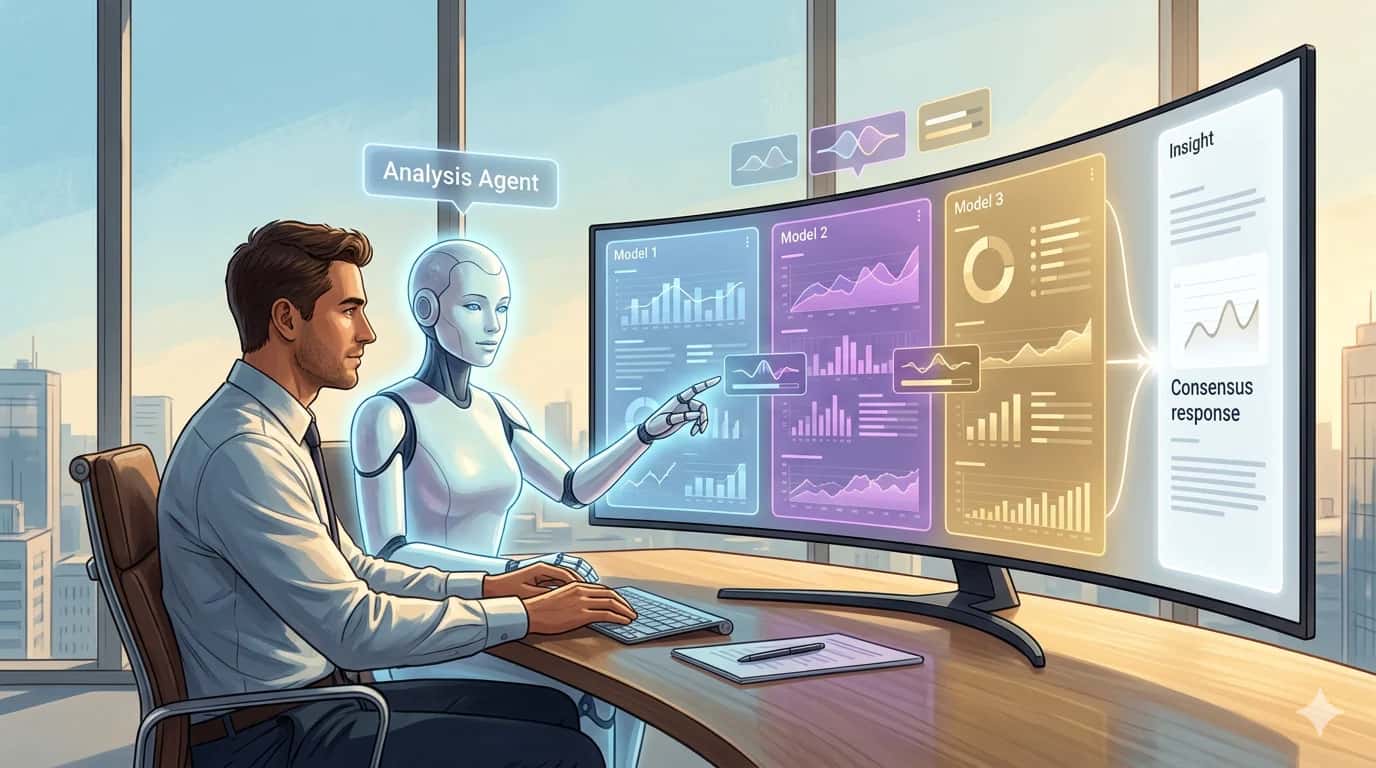
Agent Type 2: The Analysis Agent — Multi-Model Consensus as a Quality Layer
What it is: The Analysis Agent goes beyond surface-level data interpretation. It is designed to interrogate information critically — identifying patterns, surfacing contradictions, and producing structured insights that support confident decision-making. But a single model analyzing data is still a single point of failure.
That is why our Analysis Agent is built on a multi-model architecture. Rather than relying on one foundation model to interpret a dataset or evaluate a complex query, the Analysis Agent runs multiple models in parallel against the same input, then fuses their outputs into a single synthesized response. Each model functions as an independent analytical voice — and the fusion layer identifies where they agree, where they diverge, and how to produce the most reliable combined answer.
This approach is particularly powerful in regulated environments where accuracy and consistency are non-negotiable. When models disagree on an analytical output, that disagreement itself becomes a signal — a natural trigger for human review or escalation rather than a silent failure buried inside a confident-sounding response.
We have built a multi-model platform on exactly this principle, currently in initial testing. You can explore it at inferch.ai. The early results are compelling — not just in output quality, but in the visibility it provides into model behavior and confidence levels during analysis.
What can go wrong:
- Consensus on the wrong answer — models can converge confidently on the same incorrect analytical conclusion, particularly when they share similar training data or biases
- Fusion dilution — a strong, accurate insight from one model can be weakened when averaged against less precise outputs from others
- Inconsistent interpretation — different models may read the same dataset through different assumptions, producing outputs that are difficult to reconcile cleanly
- Cost and latency trade-offs — running multiple models simultaneously increases computational cost and response time, which must be factored into deployment design — particularly for high-frequency analytical workloads
The multi-model Analysis Agent is not the right architecture for every use case. But for high-stakes analytical tasks — financial risk assessment, compliance review, clinical data interpretation — it introduces a layer of validation and auditability that single-model deployments simply cannot provide. Analysis becomes not just faster, but more defensible.
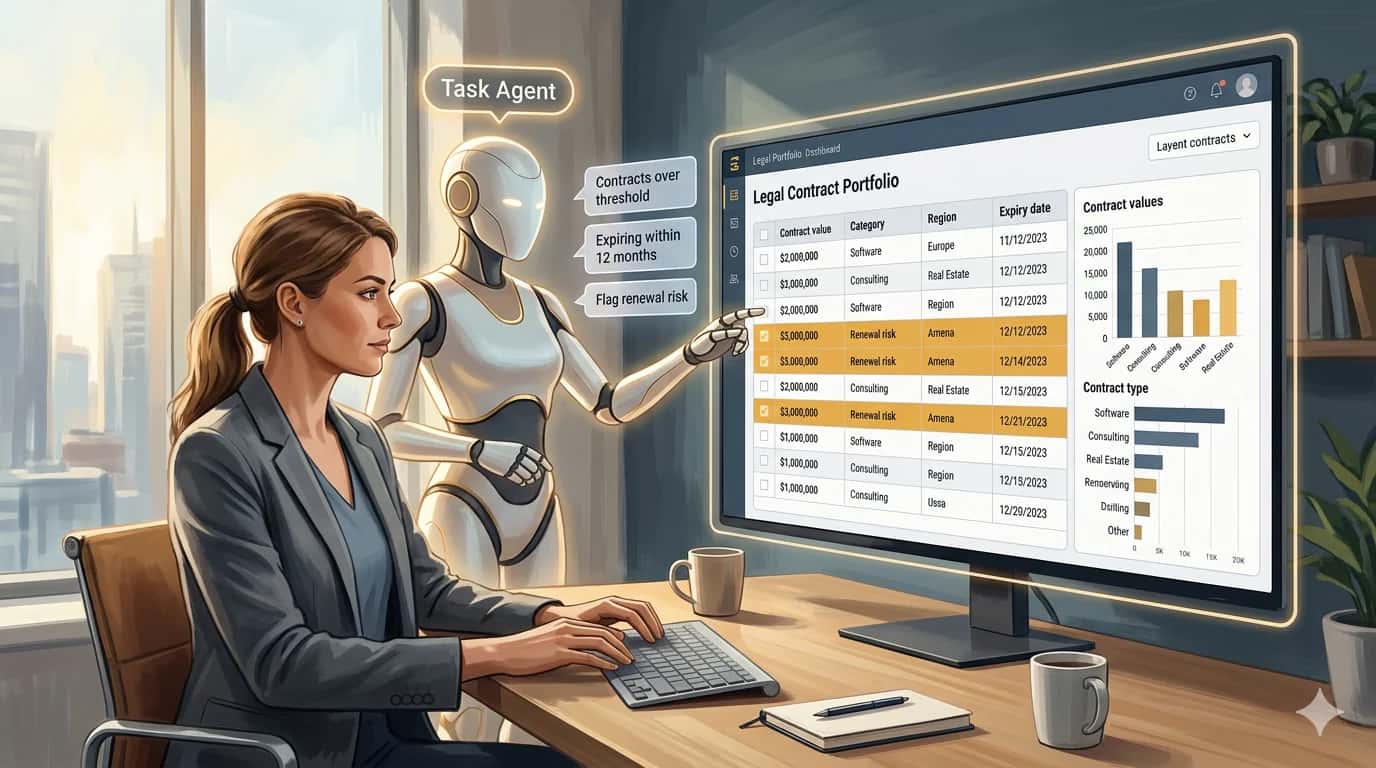
Agent Type 3: The Task Agent — Precision Over Breadth
What it is: The task agent operates within strictly defined boundaries. It has one job, a specific dataset, and a constrained set of actions. It does not improvise. It does not wander into adjacent topics. It executes complex, multi-step analytical tasks within a well-defined scope — and it does so reliably.
A concrete example: we built an agentic flow designed exclusively to run structured queries against a portfolio of legal contracts that had already been processed and structured. The agent's brief was specific:
- Show me all contracts with a total value greater than a defined threshold
- Graph contract values by category or region
- Identify contracts expiring within the next 12 months
- Flag renewal risk based on defined criteria
These are not simple keyword searches. They require the agent to interpret natural language instructions, map them to structured data, execute the right query logic, and present the output in a usable format. But they are also not open-ended. The agent stays within its lane — and that constraint is a feature, not a limitation.
What can go wrong:
- Schema drift — if the underlying data structure changes and the agent is not updated, it can silently misinterpret fields or produce incorrect aggregations
- Filter logic errors — small mistakes in how the agent interprets query conditions can produce results that look correct but are materially wrong
- Permission leakage — without proper access controls, the agent may surface contract data that the querying user is not authorized to see
- Scope creep — as users discover what the agent can do, there is natural pressure to expand its remit beyond what it was designed and validated for
The task agent is where the line between traditional automation and intelligent agents becomes most visible — and most important to understand.
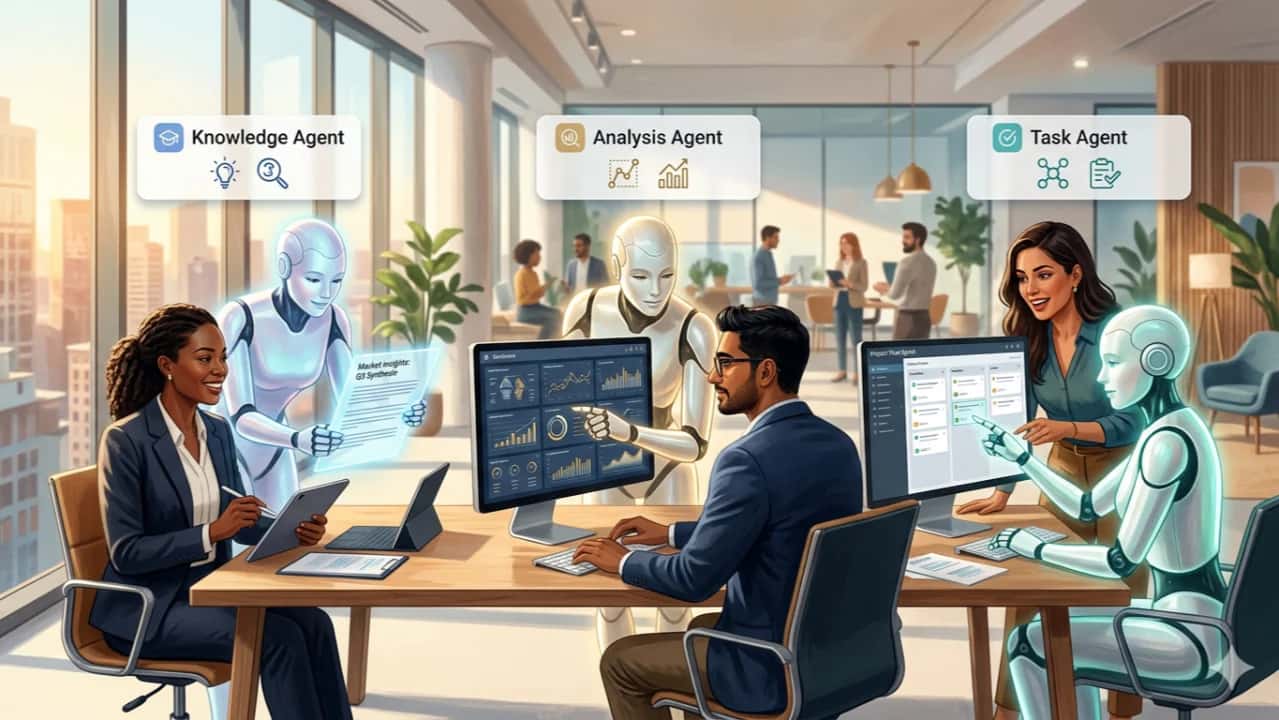
The Enterprise Agent Portfolio: Three Essential Constructs
As enterprises mature in their adoption of agentic AI, a natural portfolio of agent types emerges. Each serves a distinct function:
The Knowledge Agent Grounded in internal documents and institutional data, this agent answers questions with citations, supports compliance queries, and makes organizational knowledge accessible at scale. The RAG agent is its foundation.
The Analyst Agent Structured, data-driven, and task-specific. This agent runs queries, generates reports, surfaces patterns, and supports decision-making within defined analytical boundaries. The task agent is its core expression.
The Personal Assistant Agent Email drafting, meeting summarization, communication support. This agent operates closest to the individual user and carries its own governance requirements — particularly around data privacy and appropriate use in regulated environments.
These are not competing constructs. They are complementary layers of an enterprise AI architecture — each with its own scope, its own risk profile, and its own governance requirements.
The Non-Negotiable: Validate, Launch, Govern
In a regulated enterprise, deploying an AI agent is not a software release. It is closer to launching a monitored service with defined accountability. Every agent — regardless of type — requires the following:
Pre-launch validation
- Defined scope and explicit boundaries of what the agent will and will not do
- Testing against representative queries, including edge cases and adversarial inputs
- Review by domain experts, compliance teams, and where relevant, legal counsel
- Clear documentation of data sources, model versions, and retrieval configurations
The governing principle is simple: no agent without observability. In regulated industries, an agent you cannot monitor is a liability you cannot manage.
Closing Thought: Intelligence Requires Accountability
AI agents represent a genuine shift in what enterprise software can do. The knowledge agent that makes your compliance library conversational, the analyst agent that turns contract management into a real-time query interface, the multi-model platform that introduces consensus as a quality layer — these are not incremental improvements. They are architectural changes in how organizations access and act on information.
The governing principle is simple: no agent without observability. In regulated industries, an agent you cannot monitor is a liability you cannot manage.